Introduction
Eighteen months ago, picking “the best AI model” meant choosing between three or four chatbots that all did roughly the same thing at roughly the same price. That era is over. By mid-2026, the frontier has fractured into specialists: one lab leads coding, another leads scientific reasoning, a third undercuts everyone on price, and a fourth has quietly become the cheapest way to get near-frontier intelligence without paying frontier rates.
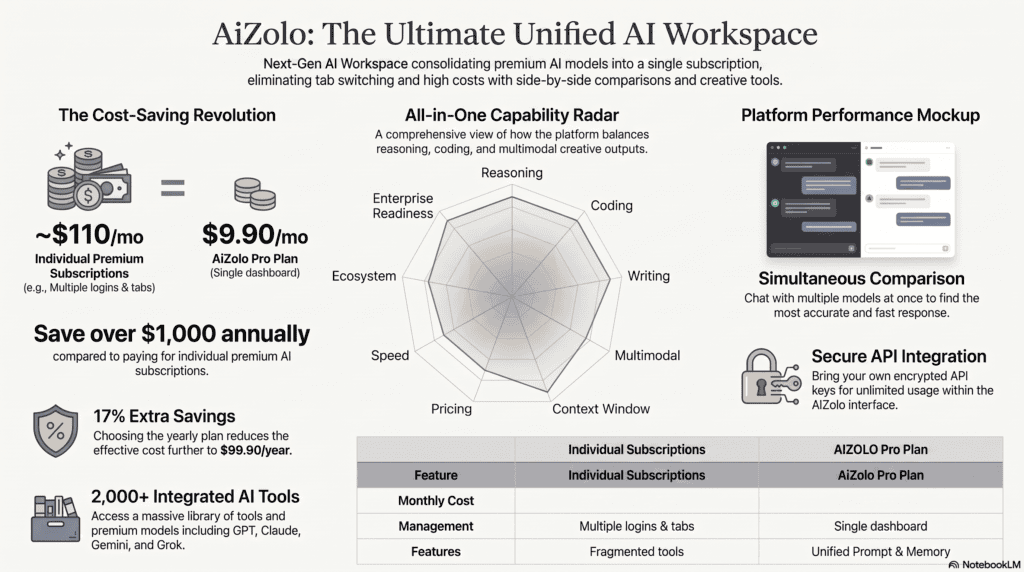
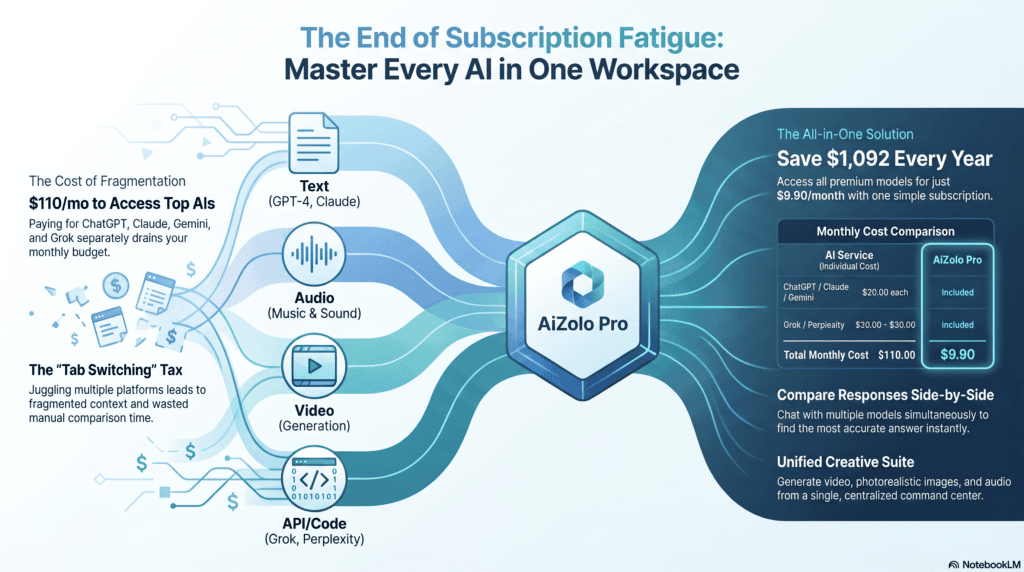
Platforms like AiZolo make this shift easier to navigate by putting multiple leading models in one place. No single model wins every category anymore, and pretending otherwise is how most “best AI” roundups mislead readers.
This guide exists because most competitor content on this topic is either outdated within weeks of publishing, recycled from a single vendor’s marketing page, or padded with generic “AI is changing everything” filler that never answers the question a reader actually has: which model should I use, for what, and how much will it cost me?
We evaluated the current frontier lineup — OpenAI’s GPT-6 Astra, Anthropic’s Claude Opus 4.8, Google’s Gemini 3.8 Flash, xAI’s Grok 4.6, and DeepSeek’s V4.1-Flash — against a consistent set of criteria: reasoning ability, coding performance, writing quality, multimodal capability, context window, pricing, API availability, and real-world reliability. We also flag where each model has genuine weaknesses, because a guide that only lists strengths isn’t useful — it’s advertising.
One important caveat before we start, and we’ll repeat it throughout: AI model releases, pricing, and benchmark scores change fast — sometimes within the same month. Every figure below reflects the most recent verifiable data as of mid-2026, but you should always confirm current pricing and specs directly from each provider before making a purchasing decision. We link to official sources throughout for exactly that reason.
If your actual goal is to stop paying for five different subscriptions and instead access every model from one place, that’s a separate (and increasingly common) decision — we cover it in the best AI subscription section near the end.
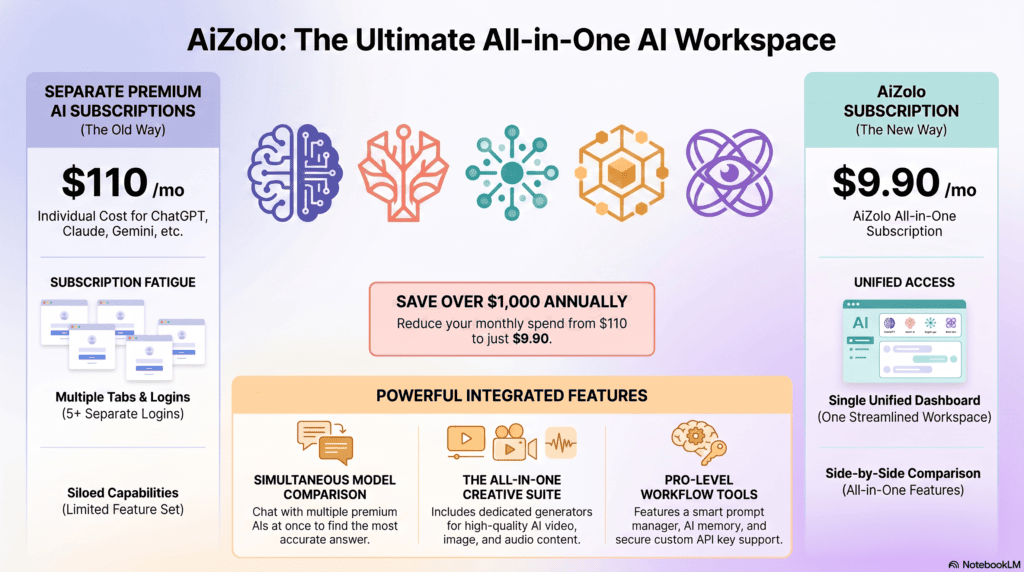
Table of Contents
How We Selected These Top 5 AI Models
Dozens of AI models are technically “frontier-class” in 2026 — Meta’s Llama 4, Alibaba’s Qwen 3.8 Max, Z.AI’s GLM-5.1, MiniMax M3, and others all have legitimate claims to a top-10 spot (our AI comparison chart lines up ten of the most-used models, including several outside this top 5, on pricing, context window, and speed). We narrowed the field to five by weighting the factors that actually determine whether a model is useful in production, not just impressive on a leaderboard:
- Reasoning depth — performance on graduate-level science (GPQA Diamond), abstract pattern reasoning (ARC-AGI-2), and expert-level exams (Humanity’s Last Exam)
- Coding ability — SWE-bench Verified/Pro, Terminal-Bench, and real-world agentic coding reliability inside tools like Claude Code, Codex, and Cursor
- Writing and creativity — prose quality, tone control, and long-form coherence, judged qualitatively since no benchmark fully captures this
- Multimodal range — image, audio, video input and, where relevant, image generation and voice
- Context window — how much text, code, or media the model can process in a single request
- Pricing and API availability — per-token cost, free-tier access, and enterprise terms
- Speed and latency — time-to-first-token and output throughput, which matter enormously for agentic and real-time use
- Ecosystem and tooling — how well the model integrates into IDEs, browsers, and existing developer workflows
- Privacy and enterprise readiness — data handling policies, compliance certifications, and deployment options (API, cloud marketplace, on-prem for open-weight models)
- Independent benchmark performance — we prioritized third-party evaluators (Artificial Analysis, LMSYS/Chatbot Arena, SWE-bench, LiveBench) over vendor self-reported numbers wherever both existed
Did You Know? Reasoning models — the kind that “think” before answering — tend to hallucinate at a higher rate than simpler, non-reasoning models on some fact-checking benchmarks, not a lower one. Depth of reasoning and factual reliability are related but not the same thing, and it’s worth testing both before trusting a model with anything high-stakes.
The five models that consistently led across this scoring, and that appear across nearly every independent benchmark tracker we reviewed, are GPT-6 Astra, Claude Opus 4.8, Gemini 3.8 Flash, Grok 4.6, and DeepSeek V4.1-Flash. If you’re comparing your own shortlist, our AI subscription price comparison breaks down consumer plan costs across all five.
Top 5 AI Models in 2026 — Full Comparison Table
| Model | Developer | Latest Version | Best For | Context Window | Input / Output Price (per 1M tokens) | Free Tier |
|---|---|---|---|---|---|---|
| GPT-6 Astra | OpenAI | September 2026 | Advanced reasoning, agents, coding, complex tasks | 1M (1.05M) | $4 / $20 | Yes, limited |
| Claude Opus 4.8 | Anthropic | May 2026 | Coding, careful reasoning, long agent sessions | 1M | $5 / $25 | No (Free tier runs Sonnet) |
| Gemini 3.8 Flash | September 2, 2026 | Coding, agents, reasoning, knowledge work, multimodal tasks | 1M | $2 / $12 | Yes | |
| Grok 4.6 | xAI | April/May 2026 | Real-time data, video input, low-cost agentic use | 1M | $1.25 / $2.50 | Limited |
| DeepSeek V4.1-Flash | DeepSeek | Septamber 2026 (preview) | Coding, reasoning, cost-efficient AI | 1M | $0.44 / $0.87 | Yes, free web chat |
Pricing reflects standard API rates at publication and excludes promotional or introductory pricing, which several vendors currently offer. Always verify current rates on the official pricing pages linked in each section, since vendors update these frequently.
Quick Summary: If you want one model that’s good at almost everything, GPT-6 Astra or Claude Opus 4.8 are the safest defaults. If cost-per-token is your primary constraint, DeepSeek V4.1-Flash or Gemini 3.8 Flash deliver most of the capability at a fraction of the price. If you need native video understanding or real-time web/social context, Grok 4.6 is the only model built specifically for that.
Which Model Wins Each Category? Quick Reference
Before the full breakdowns below, here’s the fast version — which model leads by category, based on the same evaluation criteria above.
| Category | Winner | Runner-Up |
|---|---|---|
| Coding (deep, multi-file, agentic) | Claude Opus 5 | GPT-6 Astra |
| Scientific & abstract reasoning | Gemini 3.8 Flash | Claude Opus 5 |
| Long-form writing quality | Claude Opus 5 | GPT-6 Astra (Canvas editing) |
| Real-time information | Grok 4.6 | — |
| Multimodal input (video/audio/image) | Gemini 3.8 Flash | GPT-6 Astra |
| Cost efficiency / value | DeepSeek V4.1-Flash | Grok 4.6 |
| Broadest ecosystem / all-purpose default | GPT-6 Astra | Claude Opus 5 |
Grok 4.5 (July 2026) shifted focus toward coding and agentic workflows and no longer ships native video input the way Grok 4.3 did — its real-time-data edge (live X integration) remains, but it’s a narrower multimodal story than the prior version.
No model wins every row — which is exactly the point of this guide. The section below breaks down why.
1. GPT-6 Astra (OpenAI)
Model Overview
GPT-6 Astra is OpenAI’s flagship model, released in September 2026 as a successor to GPT-6 Astra. It’s built specifically for long-horizon agentic work — planning, tool use, and multi-step tasks that run for minutes or hours without constant human intervention — while matching GPT-6 Astra’s per-token serving latency despite being meaningfully more capable.
Best For
Agentic coding and tool use, broad general-purpose tasks, and teams already invested in the OpenAI/Codex ecosystem.
Key Features
- 1M-token context window (1.05M in practice) with 128K max output
- GPT-6 Astra variant for research-grade math and science work
- Deployed inside ChatGPT, Codex, and the API simultaneously
- Deep integration with Codex for software engineering workflows, where OpenAI reports over 85% internal weekly adoption
Strengths
- Broadest ecosystem of any model here — third-party integrations, plugins, and enterprise tooling are more mature than any competitor
- Strong, well-rounded performance across coding, writing, and general reasoning rather than excelling narrowly
- Meaningful reliability gains: OpenAI reports GPT-6 Astra Instant produces roughly half as many hallucinated claims as its immediate predecessor on flagged high-stakes prompts
- GPT-6 Astra pushes the frontier on abstract mathematics, contributing to a documented new proof in Ramsey number theory
Weaknesses
- Premium pricing relative to Gemini 3.8 Flash and DeepSeek V4.1-Flash — roughly 2.5x Gemini’s input cost
- Prompts over 272K input tokens trigger a pricing surcharge (2x input, 1.5x output) for the entire session, which catches teams off guard on long-document workflows
- Free-tier access is limited; full capability requires Plus ($20/month) or higher
- OpenAI has flagged GPT-6 Astra’s cybersecurity capability as “High” under its Preparedness Framework, meaning stricter safety classifiers are now active — occasionally at the cost of over-refusing benign requests
Latest Version
GPT-6 Astra(released September, 2026); GPT-6 Astra available for the highest-accuracy tier.
Supported Modalities
Text and image input, text output. No native audio or video input at the base tier (unlike Gemini or Grok).
Pricing
Claude Fable 5.1: $5 / $30 per million input/output tokens (standard). GPT-6 Astra: $30 / $180 per million input/output tokens. ChatGPT: Free (limited), Plus $20/month, Pro $100–$200/month depending on the usage tier.
API Availability
Yes — Chat Completions and Responses APIs, with Batch (50% discount) and Priority (2.5x) pricing tiers.
Context Window
1M tokens (1.05M), 128K max output.
Coding Ability
Very strong. 82.7% on Terminal-Bench 2.0 and 73.1% on OpenAI’s internal Expert-SWE long-horizon benchmark. Powers Codex, which OpenAI says over 85% of its own staff use weekly.
Writing Quality
Strong, versatile prose across formats; Canvas editing environment is well-regarded for collaborative drafting and revision.
Reasoning Performance
Top-tier on the Artificial Analysis Intelligence Index (around 60, among the highest tracked). GPT-6 Astra leads on FrontierMath Tier 4, the hardest published mathematics benchmark.
Image Generation
Not native to the GPT-6 Astra chat model — image generation is handled by OpenAI’s separate image models, accessible through ChatGPT and the API.
Voice Support
Available through ChatGPT’s voice mode and the Realtime API, though not natively unified into the core GPT-6 Astra model in the way Gemini’s is.
Ideal Users
Enterprises and developers who want the most mature ecosystem and are willing to pay a premium for it; teams running complex agentic coding pipelines through Codex.
Real-World Use Cases
OpenAI cites internal examples including a finance team reviewing tens of thousands of K-1 tax forms in a fraction of the usual time, and go-to-market staff automating weekly business reporting.
Expert Verdict
GPT-6 Astra is the safest “default” pick if you want one model to handle almost everything reasonably well and you value ecosystem maturity over rock-bottom pricing. It isn’t the cheapest, the single best coder, or the top reasoning model on every benchmark — but it’s rarely more than a few points behind the leader in any category, which is a hard combination to beat.
Overall Rating
4.6 / 5
2. Claude Opus 4.8 (Anthropic)
Model Overview
Claude Opus 4.8 is Anthropic’s flagship model, released May 28, 2026, building on Opus 4.7. It’s positioned as the most reliable model for complex, accuracy-critical agentic work — long coding sessions, browser and computer-use agents, and tasks where the last few percentage points of correctness matter more than speed or cost. Anthropic also offers Claude Sonnet 5, a mid-tier model released a month later that closes much of the capability gap at a significantly lower price, and Claude Fable 5, a higher-capability model above Opus in Anthropic’s lineup for the hardest workloads.
Best For
Software engineering, long multi-step agent sessions, computer-use automation, and careful reasoning through ambiguous or high-stakes prompts.
Key Features
- 1M-token context window by default across the API, Bedrock, Google Cloud, and Microsoft Foundry
- Adaptive thinking with an adjustable “effort” parameter (low/medium/high/xhigh) instead of manually set thinking budgets
- Fast mode (research preview) offering up to 2.5x higher output throughput at premium pricing
- Roughly four times less likely than Opus 4.7 to let flaws in its own generated code pass unremarked, per Anthropic’s internal evaluation
- Powers Claude Code, Cursor, and Windsurf as a preferred backend for professional developers
Strengths
- Leads or ties for the lead on coding benchmarks: 69.2% SWE-bench Pro, 88.6% SWE-bench Verified
- Best-in-class computer-use and browser-agent performance — 83.4% on OSWorld-Verified, the only model in this comparison to complete every case end-to-end on Hebbia’s Super-Agent benchmark
- Strong, natural long-form prose that many writers and editors prefer over competitors
- Anthropic reports the model pushes back on weak or underspecified prompts rather than blindly complying, which reduces downstream errors on ambiguous tasks
Weaknesses
- Most expensive per-token pricing of the five flagships at standard rates ($5/$25), though Sonnet 5 offers a cheaper path to similar quality on many tasks
- Not available on Anthropic’s free tier (Free and Pro default to Sonnet 5; Opus 4.8 requires Pro-tier access or above)
- No native image generation and limited native voice support compared to Gemini or Grok
- Extended thinking budgets are deprecated in favor of the effort parameter, which requires a small migration for teams upgrading from older Claude versions
Latest Version
Claude Opus 4.8 (May 28, 2026). Claude Sonnet 5 (June 30, 2026) is the current mid-tier model and default on Free/Pro plans; it beats Sonnet 4.6 on every published benchmark and even edges out Opus 4.8 on applied knowledge-work tasks (GDPval-AA), while costing roughly 40–60% less per token.
Supported Modalities
Text and image input, text output, vision.
Pricing
$5 / $25 per million input/output tokens (Opus 4.8 standard); Fast mode $10/$50. Sonnet 5: $3/$15 standard, with introductory pricing of $2/$10 through August 31, 2026. Claude Pro (consumer): $20/month.
API Availability
Yes — Claude API, Amazon Bedrock, Google Cloud, and Microsoft Foundry.
Context Window
1M tokens, 128K max output (up to 300K on the Batch API with the extended-output beta).
Coding Ability
Best-in-class among the five for deep, multi-file software engineering: 69.2% SWE-bench Pro, 88.6% SWE-bench Verified, and strong CursorBench performance.
Writing Quality
Widely regarded as the most natural, least “AI-sounding” prose generator of the group, particularly for long-form and nuanced tone work.
Reasoning Performance
Strong across the board; leads on long-horizon agentic reasoning using adaptive thinking, though Gemini 3.8 Flash currently edges it on some pure-science benchmarks like GPQA Diamond.
Image Generation
Not supported natively.
Voice Support
Limited compared to Gemini/Grok; primarily accessed through third-party integrations rather than a native voice mode.
Ideal Users
Professional software teams, technical writers, and anyone running long autonomous agent sessions where a single mistake late in a task is costly to unwind.
Real-World Use Cases
Zapier reportedly used Sonnet 5 to complete a two-part business automation task — updating CRM account tiers and sending a targeted launch email — end to end without manual intervention. Opus 4.8 is commonly deployed for large-scale codebase refactors and QA review pipelines.
Expert Verdict
If your work is coding-heavy, agent-heavy, or both, Claude Opus 4.8 is very likely the strongest single choice in this list — but test Sonnet 5 first for routine work, since it captures most of Opus’s capability at 40–60% of the cost and is now the more practical daily driver for many teams.
Overall Rating
4.8 / 5
For a deeper breakdown of Anthropic’s current lineup and how to route work between Sonnet 5 and Opus 4.8, see the platforms where multiple AI models answer the same question approach many teams now use to A/B test both simultaneously.
3. Gemini 3.8 Flash (Google)
Model Overview
Gemini 3.8 Flash is Google’s most advanced reasoning model in the Gemini 3 series, released into preview on Septemper 2, 2026. It’s the first “.1” mid-cycle increment Google has used (previous generations used “.7”), reflecting a targeted but substantial reasoning upgrade rather than a full architecture overhaul. It’s built to comprehend very large, mixed-modality inputs — full codebases, hours of audio, and long video — within a single request.
Best For
Multimodal analysis, scientific and abstract reasoning, and teams that want frontier-level capability without frontier-level pricing.
Key Features
- Native multimodal input: text, image, audio, video, and code in one 1M-token context window
- Configurable thinking levels, including a new “Medium” tier for cost optimization
- Deep integration with Google Workspace, NotebookLM, AI Studio, and Vertex AI
- Strong native SVG and structured code-to-visual generation
Strengths
- Leads on abstract reasoning (77.1% ARC-AGI-2, more than double Gemini 3 Pro) and graduate-level science (94.3% GPQA Diamond, among the highest scores reported on that benchmark)
- Best price-to-capability ratio among the closed frontier models at $2/$12 per million tokens — the same price as the previous generation despite a large capability jump
- Genuinely native multimodal input, not a bolted-on vision encoder — audio and video understanding are core capabilities, not add-ons
- Deepest integration into an existing productivity ecosystem (Gmail, Docs, Drive, Sheets) for organizations already on Google Workspace
Weaknesses
- Still in preview status as of this writing, meaning Google has not yet committed to full production SLA coverage the way GA models typically carry
- Max output capped at 64K–65K tokens, notably lower than GPT-6 Astra or Claude’s 128K
- Trails Claude on expert-task human preference evaluations (GDPval-AA) and trails specialized coding models like GPT-6 Astra/Codex on some terminal-based coding benchmarks
- Pricing roughly doubles for prompts beyond 200K tokens, which is easy to miss when estimating costs for long-document workloads
Latest Version
Gemini 3.8 Flash,
Supported Modalities
Text, image, audio, video, and code input; text output.
Pricing
$2 / $12 per million input/output tokens (up to 200K tokens); $4/$18 beyond that threshold. Gemini Advanced consumer plan: $19.99/month.
API Availability
Yes — Google AI Studio, Vertex AI, Gemini CLI, and the Gemini Enterprise Agent Platform.
Context Window
1M tokens input, up to 64K–65K tokens output.
Coding Ability
Strong and improving fast: 80.6% SWE-bench Verified, a LiveCodeBench Pro Elo of 2887. It trails specialized coding models like GPT-6 Astra/Codex-class models specifically on Terminal-Bench-style command-line tasks.
Writing Quality
Solid and workmanlike rather than a standout; well-suited to structured business writing and Docs-integrated workflows rather than the most literary or nuanced prose.
Reasoning Performance
Class-leading on several major reasoning benchmarks — ARC-AGI-2 and GPQA Diamond in particular.
Image Generation
Supported through Google’s broader Gemini app ecosystem (Imagen integration), though not benchmarked here as a core text-model capability.
Voice Support
Strong native audio understanding and Google has continued refining text-to-speech capabilities across the Gemini app.
Ideal Users
Teams already inside the Google ecosystem, researchers working with large mixed-media datasets, and cost-conscious teams that still want frontier-level reasoning.
Real-World Use Cases
Long-document and full-codebase analysis, multimodal research workflows (e.g., analyzing a recorded meeting plus its slide deck plus a spreadsheet in one request), and agentic finance/spreadsheet automation.
Expert Verdict
Gemini 3.8 Flash is the best all-around value in the closed frontier tier right now. If you don’t have a strong reason to pay a premium for Claude or GPT-6 Astra, Gemini 38 Flash will cover the large majority of use cases at roughly 60% less cost per token.
Overall Rating
4.6 / 5
4. Grok 4.6 (xAI)
Model Overview
Grok 4.3 is xAI’s reasoning-first flagship, which entered beta on July 17, 2026 and opened to the general API on July 30, 2026. It folds always-on chain-of-thought reasoning into its base behavior rather than offering it as a togglable mode, and it’s the only model in this group with native video input.
Best For
Real-time, socially grounded information; native video analysis; and cost-sensitive agentic or tool-use workloads.
Key Features
- 1M-token context window (a separate Grok 4.20 variant offers a 2M-token window for extreme long-context needs)
- Native video input (mp4/mov/webm, up to 5 minutes, 1080p) without requiring upstream frame extraction or transcription
- Live X/Twitter data grounding built into the core model, not bolted on as a plugin
- Native artifact generation — the model can directly produce PDFs, slide decks, and spreadsheets as outputs
- Configurable reasoning-effort levels (none/low/medium/high)
Strengths
- By far the most affordable of the five flagships: $1.25/$2.50 per million tokens, roughly 4–12x cheaper than Claude Opus 4.8 or GPT-6 Astra depending on the comparison basis
- Only model here with native, real-time access to social/web trend data baked into its core architecture rather than a separate search tool
- Strong agentic and instruction-following scores: 97–98% on τ²-Bench Telecom-style tool-use tests, and a large GDPval-AA Elo jump versus its predecessor
- Native video understanding is a genuine differentiator none of the other four currently match at the base-model level
Weaknesses
- Always-on reasoning means noticeably higher time-to-first-token (roughly 20 seconds), which makes it a poor fit for latency-sensitive, sub-second use cases
- Independent evaluations have flagged elevated hallucination rates on some fast-reasoning variants — worth testing carefully before using Grok for anything fact-critical
- Smaller developer ecosystem and less mature third-party tooling than OpenAI, Anthropic, or Google
- The most advanced features (Custom Voices, Grok 4.20’s 2M-context multi-agent variant) are gated behind the pricier SuperGrok Heavy tier, not the base subscription
Latest Version
Grok 4.3, general API access from July 30, 2026.
Supported Modalities
Text, image, and native video input; text output. Voice cloning available via a separate Custom Voices suite.
Pricing
$1.25 / $2.50 per million input/output tokens; $0.20 cached input. SuperGrok consumer plan starts at $30/month; SuperGrok Heavy (full feature set) $300/month.
API Availability
Yes — OpenAI-SDK-compatible, making migration from GPT-based clients a base-URL change in most cases.
Context Window
1M tokens (Grok 4.20 variants offer up to 2M for specialized multi-agent/long-context workloads).
Coding Ability
Competitive but not category-leading; strongest in agentic tool-use and instruction-following contexts rather than deep multi-file software engineering.
Writing Quality
Distinctive, more opinionated and less filtered tone than competitors — a deliberate positioning choice by xAI rather than a limitation, though it means Grok is a poor fit for brand-safe, highly controlled corporate copy without careful prompting.
Reasoning Performance
Solidly above the median tracked reasoning model on the Artificial Analysis Intelligence Index, though it trails GPT-6 Astra and Gemini 3.8 Flash on most published composite scores.
Image Generation
Available through the broader Grok/X app ecosystem, not a core capability of the base chat model evaluated here.
Voice Support
Strong — includes a dedicated Custom Voices voice-cloning suite, a capability none of the other four models in this list currently ship natively.
Ideal Users
Teams building real-time, socially aware applications; video-heavy analysis workflows; and cost-sensitive agentic pipelines that can tolerate higher latency.
Real-World Use Cases
Extracting key events from long-form video (security footage, recorded lectures, meetings) and summarizing them chapter-by-chapter; low-cost, high-volume tool-calling agents.
Expert Verdict
Grok 4.3 isn’t trying to be the single smartest model — it’s trying to be the cheapest genuinely capable one, with a couple of real technical firsts (native video, live social grounding) that the others don’t match. It’s a strong secondary or budget-tier model, less convincing as your only model if factual reliability is critical.
Overall Rating
4.2 / 5
5. DeepSeek V4.1-Flash (DeepSeek)
Model Overview
DeepSeek V4.1-Flash is DeepSeek’s latest open-weight Mixture-of-Experts model, released on September 10, 2026. It features a 552-billion-parameter MoE architecture with 8 billion active parameters for input processing and 16 billion active parameters for output generation. The model introduces a new Causal Encoder–Decoder architecture, native multimodal visual understanding, and a 1-million-token context window. It is MIT-licensed and available on Hugging Face. DeepSeek has also made V4.1-Flash available through its API as deepseek-flash, replacing the earlier V4-Flash variants.
Best For
Cost-sensitive, high-volume production workloads; coding and AI agents; long-context research; multimodal document and image analysis; and teams that want strong frontier-level performance at substantially lower inference costs.
Key Features
- DeepSeek V4.1-Flash is a 552-billion-parameter Mixture-of-Experts (MoE) model with 8B active parameters during input processing and 16B during output generation.
- Uses a new Causal Encoder–Decoder (CED) architecture designed to reduce KV-cache requirements and improve inference efficiency.
- Supports a 1-million-token context window and maximum generation of at least 256K tokens.
- Supports native image + text input, with text output, making it a multimodal model rather than the text-only model described in the previous version.
- Provides continuously controllable reasoning effort from 1 to 100, allowing developers to adjust reasoning depth per request.
- Available under the MIT license, with model weights released on Hugging Face.
- The official API model ID is
deepseek-flash. DeepSeek says previousdeepseek-v4-flashanddeepseek-v4-flash-vision-exprequests temporarily route to V4.1-Flash for compatibility. - Supports integration through modern API formats and tooling, including OpenAI-compatible interfaces and DeepSeek’s own API tooling.
Strengths
- Exceptional price-performance: DeepSeek specifically designed V4.1-Flash around lower inference cost, faster inference, and higher throughput.
- Efficient long-context processing: The model supports a 1M-token context while using substantially less persistent KV-cache storage than the previous generation.
- Strong coding and agent performance: DeepSeek reports competitive results across software-engineering and agentic benchmarks, including DeepSWE and other code-agent evaluations.
- Native visual understanding: Unlike the earlier text-only description, V4.1-Flash can process images together with text, enabling document, chart, screenshot, and visual-agent workloads.
- Open weights: The MIT license gives developers considerable freedom to inspect, modify, deploy, and self-host the model.
- Adjustable reasoning: Reasoning effort can be continuously controlled from 1 to 100, allowing teams to balance quality, latency, and cost.
Weaknesses
- Very large model: Although MoE activation is relatively efficient, the overall model is still extremely large, making self-hosting substantially more demanding than deploying a conventional smaller open-weight model.
- Deployment complexity: Running the full model locally requires specialized infrastructure and optimized inference software; for many teams, using the API or hosted inference will be more practical.
- Preview-era ecosystem: The latest V4.1-Flash release is very new, so third-party tooling, benchmarks, and deployment support are still developing.
- Data-residency considerations: Organizations in regulated industries should evaluate where their API requests are processed and stored before using DeepSeek for sensitive workloads.
- Benchmark comparisons require caution: DeepSeek’s published results use specific reasoning settings and agent harnesses, so direct comparisons with competitors should account for evaluation methodology.
Latest Version
DeepSeek V4.1-Flash — September 10, 2026.
DeepSeek’s latest release is the V4.1-Flash model. The earlier V4-Flash and V4-Flash-Vision-Exp have been retired, while DeepSeek says V4-Pro is being phased out. Starting September 14, 2026, requests to deepseek-v4-pro are scheduled to route to V4.1-Flash at V4.1-Flash pricing until V4.1-Pro launches.
Supported Modalities
Image + text input; text output.
DeepSeek V4.1-Flash has native visual understanding, so the previous description of it as a text-only base model should be removed. The released model includes a dedicated vision encoder and can process images alongside text.
Pricing
DeepSeek V4.1-Flash: $0.14 per million input tokens and $0.28 per million output tokens under the current API pricing. The model is also available through DeepSeek’s web chat at no charge, subject to applicable usage limits. The earlier V4-Pro ($0.435 / $0.87) and V4-Flash ($0.14 / $0.28) pricing referred to the previous V4 preview variants and should not be presented as the current V4.1-Flash model lineup.
API Availability
Yes. DeepSeek V4.1-Flash is available through DeepSeek’s API and supports compatibility with OpenAI-compatible Chat Completions and modern developer tooling. The official API model ID is deepseek-flash.
Context Window
1 million tokens of context, with a maximum output of at least 256K tokens. This makes V4.1-Flash particularly suitable for large codebases, long documents, and extended agentic workflows.
Coding Ability
V4.1-Flash is designed for advanced software engineering and coding-agent workloads. DeepSeek reports strong performance on software-engineering and agent benchmarks, while its MoE architecture keeps active computation considerably smaller than its total parameter count.
Writing Quality
V4.1-Flash is capable of producing strong technical, structured, and general-purpose writing. It is particularly attractive for developers and teams that need high-volume content generation at a low per-token cost. Its Chinese-language capabilities are also a notable strength.
Reasoning Performance
The model supports continuously adjustable reasoning effort from 1 to 100, allowing developers to trade off reasoning depth, latency, and cost. DeepSeek positions V4.1-Flash as a strong model for mathematics, coding, research, and complex multi-step reasoning.
Image Generation
Not supported. V4.1-Flash provides native image understanding as an input capability, but it does not generate images.
Voice Support
Not supported natively. V4.1-Flash is primarily a text-output model and does not provide built-in speech generation or voice conversation.
Ideal Users
Engineering teams looking to minimize inference costs, developers building high-volume AI agents and coding tools, organizations interested in open-weight deployment, and teams that need long-context reasoning and image understanding without paying frontier-model prices.
Real-World Use Cases
V4.1-Flash is well suited to large-scale code review and refactoring, software-engineering agents, customer-support automation, document analysis, research workflows, long-context data processing, and other workloads where low cost and high throughput matter.
Expert Verdict
DeepSeek V4.1-Flash demonstrates how quickly the open-weight AI ecosystem is closing the gap with proprietary frontier models. Its combination of a 1-million-token context window, native visual understanding, adjustable reasoning, strong coding and agent capabilities, and extremely low API pricing makes it one of the most compelling cost-efficient models of 2026. Its relatively new release and demanding self-hosting requirements remain important considerations for production deployments.
Overall Rating
4.5 / 5
Benchmark Comparison: Reasoning, Coding, Math, and More
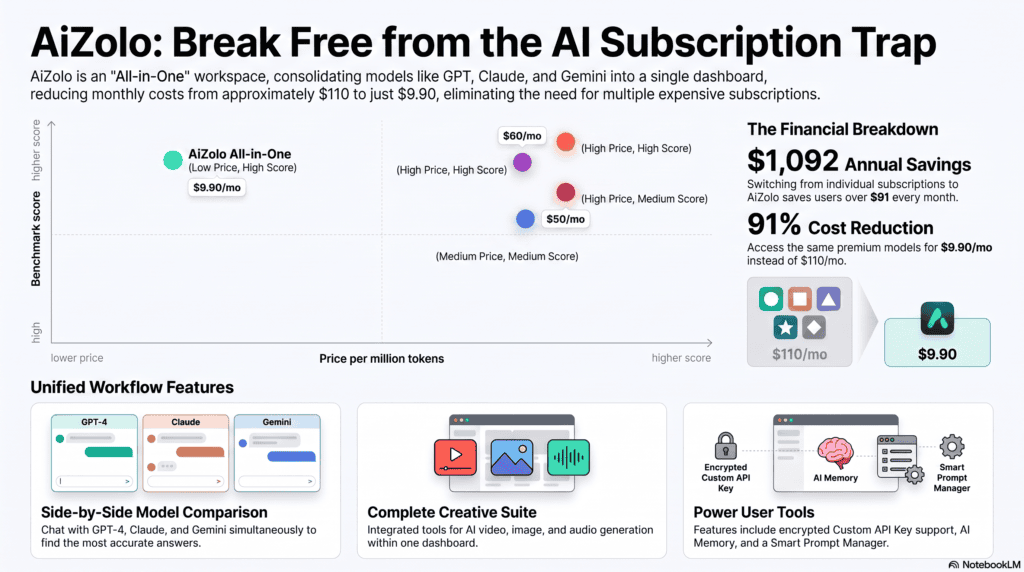
Benchmark numbers move fast and vendors sometimes report figures under different test conditions, so treat this table as directional rather than exact — and re-check current numbers before citing them in anything formal.
| Benchmark | GPT-6 Astra | Claude Opus 4.8 | Gemini 3.8 Flash | Grok 4.6 | DeepSeek V4.1-Flash |
|---|---|---|---|---|---|
| SWE-bench Verified (coding) | Strong (not disclosed at launch) | 88.6% | 80.6% | Competitive, not category-leading | ~80.6% (tied) |
| SWE-bench Pro (coding) | Strong | 69.2% | — | — | Competitive |
| Terminal-Bench 2.0 (agentic coding) | 82.7% | 82.7% (per some trackers) | Trails GPT-6 Astra/Codex-class models | Competitive | — |
| GPQA Diamond (science reasoning) | Strong | Strong | 94.3% (leader) | 90.1% | 71.7% |
| ARC-AGI-2 (abstract reasoning) | — | — | 77.1% (leader) | — | — |
| Humanity’s Last Exam | Strong | ~50–58% w/ tools | Strong | Competitive | — |
| Artificial Analysis Intelligence Index | ~60 | ~61.4 (leader in some trackers) | ~46–57 | ~38–53 | ~31–39 |
| Context window | 1M | 1M | 1M | 1M (2M variant) | 1M |
| Multimodal input (video/audio/image) | Image only | Image only | Native — image, audio, video | Native — image, native video | Text only |
| Max output | 128K | 128K | 64–65K | Not capped | 384K |
| Price per 1M tokens (in/out) | $5/$30 | $5/$25 | $2/$12 | $1.25/$2.50 | $0.44/$0.87 |
Expert Tip: Don’t pick a model on a single benchmark score. GDPval-AA (applied knowledge work), SWE-bench (coding), and GPQA Diamond (science reasoning) measure genuinely different capabilities, and the leaderboard order changes depending on which one you weight. Run your own task-specific evaluation on a small sample before committing a production workload to any single model.
Common Mistake: Comparing sticker prices without accounting for tokenizer differences. Anthropic’s newer tokenizer, for example, produces roughly 30% more tokens for the same English text than its predecessor — meaning the effective cost of an equivalent request can shift even when the advertised per-token price doesn’t change. Always benchmark cost on your own representative prompts, not the headline rate.
Why “Which Model Is Smartest” Is the Wrong Question
Most comparisons — including earlier versions of this one — treat model intelligence as the only variable that matters. It isn’t.
The practitioners who get the most out of AI in 2026 aren’t the ones who found the single “smartest” model — they’re the ones who built a habit of routing: sending routine work to whichever model clears the bar most cheaply, and reserving the priciest, most capable model for the tasks where the accuracy gap actually shows up in the output.
That habit depends on being able to run models side by side instead of tab-switching between five logins — see our full breakdown of what having the world’s smartest AI side by side actually looks like in practice for how that workflow plays out day to day.
That means the model itself is only half the equation. The other half is having a workflow — a prompt library, a way to compare outputs side by side, a habit of testing two or three models against your actual task before committing — because by the time any single model earns the “smartest” label, a new release has usually already shifted the leaderboard.
With that in mind, here’s how to choose by use case.
Which AI Model Should You Choose?
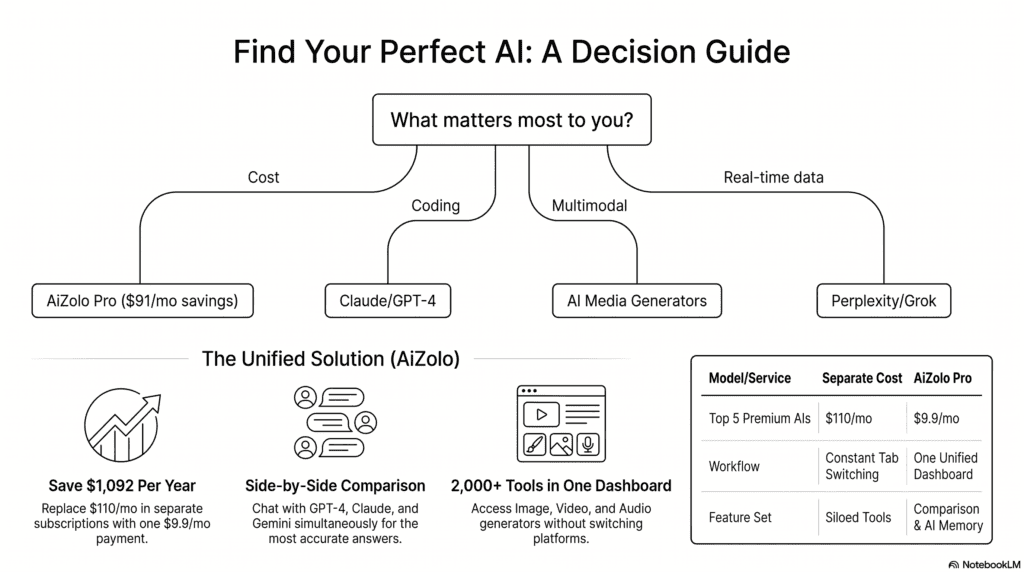
Different users have genuinely different priorities. Here’s our recommendation by use case.
Students — Gemini 3.8 Flash or Claude Sonnet 5 for research and writing help; both are affordable, capable, and Gemini’s free tier is generous for occasional use.
Developers — Claude Opus 4.8 for complex, accuracy-critical software engineering; Claude Sonnet 5 or DeepSeek V4.1-Flash for high-volume daily coding where cost matters more than the last few points of accuracy.
Researchers — Gemini 3.8 Flash for its multimodal range and leading science-reasoning benchmarks, or GPT-6 Astra for the hardest mathematics and abstract-research work.
Businesses (general) — GPT-6 Astra for the broadest ecosystem and vendor support, or Claude Opus 4.8 where document quality and reliability matter more than raw ecosystem breadth. If you’re evaluating best AI subscription services for a whole team, factor in per-seat costs alongside API costs.
Content Creators — Claude for long-form writing quality; Grok 4.6 if your content depends on real-time trends and social context.
Marketers — Gemini 3.8 Flash for its Workspace integration and multimodal campaign analysis, paired with Grok for real-time trend monitoring.
Designers — None of the five models here are primarily image generators, but Gemini 3.8 Flash’s native SVG/code-to-visual generation is the strongest fit among them for design-adjacent workflows.
Small businesses — DeepSeek V4.1-Flash or Gemini 3.8 Flash for the best capability-per-dollar; both make frontier-adjacent AI viable on a tight budget.
Large enterprises — GPT-6 Astra or Claude Opus 4.8, weighted by whether your priority is ecosystem breadth (OpenAI) or coding/agentic reliability (Anthropic); both offer enterprise-grade compliance and deployment options.
Startups — DeepSeek V4.1-Flash for burn-rate-sensitive early-stage products, upgrading to Claude Sonnet 5 or Gemini 3.8 Flash as usage and revenue scale.
Agencies — A blended approach is common: Claude for client-facing writing and creative deliverables, Gemini or DeepSeek for high-volume internal automation. This is increasingly why agencies look at a best multi-ai platform rather than committing to a single vendor.
Pro Tip: If you genuinely can’t decide, the practical answer many teams land on isn’t “pick one” — it’s routing: send routine, high-volume work to the cheapest model that clears your quality bar, and reserve the most expensive model for the specific tasks where the accuracy gap actually shows up in your metrics. Several platforms to ask the same question to multiple AI models exist specifically to make this kind of side-by-side testing easy without juggling five separate logins.
Frequently Asked Questions
1. What are the top 5 AI models in 2026? As of mid-2026, the five most consistently top-ranked frontier models are OpenAI’s GPT-6 Astra, Anthropic’s Claude Opus 4.8, Google’s Gemini 3.8 Flash, xAI’s Grok 4.6, and DeepSeek’s V4. Rankings shift as new releases land, so check for updates before relying on any single “top 5” list, including this one.
2. Which AI model is best overall in 2026? There isn’t a single universal winner. Claude Opus 4.8 and GPT-6 Astra lead most general-purpose and coding benchmarks; Gemini 3.8 Flash leads scientific and abstract reasoning at a lower price; DeepSeek V4.1-Flash leads on cost efficiency. “Best” depends entirely on your task.
3. Which AI model is best for coding in 2026? Claude Opus 4.8 currently leads most independent coding benchmarks and is the default backend inside Claude Code, Cursor, and Windsurf, with GPT-6 Astra a close second inside Codex. For a full breakdown across eleven coding-specific models — including Gemini, DeepSeek, Qwen3-Coder, and Codestral — see our best AI coding models 2026 comparison.
4. What’s the cheapest AI model with strong performance? DeepSeek V4.1-Flash, at roughly $0.14/$0.28 per million tokens, is the cheapest model in this comparison that still delivers genuinely competitive performance on coding and reasoning tasks.
5. Is Claude better than ChatGPT in 2026? For coding and long agentic sessions, independent benchmarks generally favor Claude Opus 4.8. For general-purpose breadth and ecosystem maturity, GPT-6 Astra has an edge. Many professional users run both and route tasks based on which one performs better for that specific job.
6. Is Gemini better than Claude for reasoning? On specific benchmarks like GPQA Diamond and ARC-AGI-2, Gemini 3.8 Flash currently scores higher than Claude Opus 4.8. On applied knowledge-work tasks (GDPval-AA) and expert human-preference evaluations, Claude has historically scored higher. Both are legitimate “top-tier reasoning” choices.
7. What is the context window of GPT-6 Astra, Claude, and Gemini? All three support roughly 1 million tokens of input context. Output limits differ: GPT-6 Astra and Claude Opus 4.8 cap output at 128K tokens, while Gemini 3.8 Flash caps at roughly 64K–65K tokens.
8. Does DeepSeek V4.1-Flash support image or video input? No. As of this preview release, DeepSeek V4.1-Flash is text-only. If you need native multimodal input, Gemini 3.8 Flash or Grok 4.6 are the stronger choices among the five models covered here.
9. Which AI model has the largest context window? Among the models covered here, a specialized Grok 4.20 variant offers a 2 million-token context window, the largest of any model discussed in this guide, though the standard Grok 4.3 model uses a 1M-token window like the others.
10. Which AI model is best for real-time information? Grok 4.3, because it has live X/Twitter data grounding built directly into its core architecture rather than accessed through a separate search tool.
11. Are these AI models safe to use for sensitive business data? All five providers publish data-handling policies, and most offer enterprise tiers with stronger data protections (no training on API data by default, in most cases). DeepSeek’s status as a China-based provider is a specific consideration some regulated organizations weigh separately from technical capability — review each vendor’s current data policy directly before sending sensitive or regulated data.
12. How much does it cost to use these AI models via API? Pricing ranges from roughly $0.14 per million input tokens (DeepSeek V4.1-Flash) up to $30 per million input tokens (GPT-6 Astra), depending on model and tier. Consumer chat subscriptions range from free to around $300/month for the most feature-complete individual plans.
13. Which AI model is best for students? Gemini 3.8 Flash and Claude Sonnet 5 are both strong, affordable choices for research, tutoring-style explanations, and writing support, with generous or fully free access tiers.
14. Can I use multiple AI models under one subscription? Yes — a growing number of platforms bundle access to several models under a single subscription rather than requiring separate accounts with each provider. See our single subscription multiple AI models guide for a full breakdown of how these work.
15. Which AI model produces the most natural, human-like writing? Independent qualitative reviews consistently rate Claude’s prose as the most natural and least “AI-sounding” among the five, particularly for long-form and nuanced tone work.
16. Do reasoning models hallucinate more than non-reasoning models? On some evaluation sets, yes — models using extended reasoning have shown higher hallucination rates than simpler, non-reasoning models in third-party testing. This is a real tradeoff, not a solved problem, so fact-check outputs on any high-stakes task regardless of which model you use.
17. What is the difference between Claude Opus 4.8 and Claude Sonnet 5? Opus 4.8 is Anthropic’s most capable model, leading on hard coding and reasoning tasks. Sonnet 5, released a month later, closes most of that gap — even edging ahead on some applied knowledge-work benchmarks — while costing roughly 40–60% less per token. Most teams now use Sonnet 5 as their default and escalate to Opus 4.8 only for the hardest tasks.
18. Is open-weight AI (like DeepSeek V4.1-Flash) as good as closed models? On several major benchmarks, yes — DeepSeek V4.1-Flash is now competitive with, and occasionally matches, closed frontier models on coding and knowledge tasks. It still trails on native multimodal support and production-grade SLA stability while in preview status.
19. Which AI model is best for businesses that need enterprise compliance? GPT-6 Astra and Claude Opus 4.8 currently have the most mature enterprise compliance and deployment options, including availability through major cloud marketplaces (Azure, AWS Bedrock, Google Cloud).
20. How often do these rankings change? Frequently — multiple major model releases have landed within the same single week at points in 2026. Treat any “top 5” list, including this one, as a snapshot, and check official sources before making a purchasing decision.
21. Is there a single “smartest” AI model in 2026? No. GPT-6 Astra leads advanced reasoning, Claude Fable 5.1 excels at coding and knowledge work, while Gemini 3.8 Flash stands out for multimodal and agentic tasks. The smartest model depends on your needs.
22. Which AI model is the “most intelligent” overall? There is no single winner. GPT-6 Astra currently leads several advanced reasoning benchmarks, while Claude Fable 5.1 excels at complex knowledge work. Gemini 3.8 Flash is also highly competitive, especially for coding and multimodal tasks.
23. Does the “best” AI model change depending on the task? Yes, consistently. This is the central finding across every independent benchmark tracker: no single model leads coding, reasoning, writing, multimodal, and real-time categories simultaneously. Treat “best” as a per-task question rather than a fixed ranking, and re-test periodically as new versions ship.
Conclusion
There is no single “best” AI model in 2026 — there’s a best model for your specific task, budget, and risk tolerance, and that answer will likely keep changing every few months. What we can say with confidence: Claude Opus 4.8 currently leads coding and long agentic work; Gemini 3.8 Flash offers the best combination of reasoning power and price; GPT-6 Astra remains the safest broad, ecosystem-mature default; Grok 4.3 is the cost-effective pick for real-time and video-heavy use cases; and DeepSeek V4.1-Flash has permanently changed the economics of what “good enough” AI costs at scale.
The practical takeaway for most readers: don’t marry one model. Test two or three against your actual workload, pay attention to cost-per-task rather than sticker price, and revisit your choice every quarter — because by the time you finish reading a “definitive” AI comparison guide, including this one, a new model release has probably already shifted the leaderboard. If managing several subscriptions to do that testing sounds like a hassle, that’s exactly the gap that best value AI subscription and access all AI models in one place platforms are now built to solve.
Author Bio
Jeevesh Tripathi AI Researcher & SEO Content Strategist at Aizolo
Jeevesh researches the latest AI models, benchmarks, productivity tools, and enterprise AI platforms. His work focuses on helping readers make informed decisions through hands-on testing, comparative analysis, and evidence-based content aligned with Google’s E-E-A-T principles.
Contact: jeevesh@aizolo.com