
If you write code for a living, you’ve probably already tried both models. This isn’t a listicle.
It’s a breakdown built from official benchmarks, documented pricing, and the actual behavioral differences that show up when you use Claude Sonnet 5.5 and Gemini 3.1 Pro inside a real IDE, on a real repository, for more than a single afternoon.
Both are frontier-class coding models. Neither is universally “better.” The right pick depends on your language, your repo size, your budget, and whether you’re doing greenfield generation or long-running maintenance work on an existing codebase.
Aizolo helps you compare these strengths side by side, making it easier to choose the model that best fits your development workflow.
Latest 2026 update
- Claude Sonnet 5.5 improves coding reliability and agent workflows over Sonnet 5.
- Gemini 3.1 Flash expands reasoning and long-context performance over Gemini 3.1 Pro.
- If choosing a model for a new deployment in late 2026, evaluate the latest generation first; the rest explains the architectural tradeoffs behind the earlier matchup.
Table of Contents
Quick Comparison Table
| Claude Sonnet 5.5 | Gemini 3.1 Pro | |
|---|---|---|
| Released | September 28, 2026 | February 19, 2026 |
| SWE-Bench Verified | — | 80.6% |
| Context window | 1M tokens | 1M tokens |
| Input pricing | $2 / million tokens | $2 / million tokens (≤200K) |
| Output pricing | $10 / million tokens | $12 / million tokens (≤200K) |
| Long-context pricing | Same rate | $4 / $18 per million above 200K |
| Terminal-Bench | 70.6% | 68.5% |
| Standout strength | Fast coding, bug fixing, agent workflows | Advanced reasoning, multimodal tasks, long-context analysis |
| Best for | Coding, editing, agentic workflows, fast iteration | Complex reasoning, whole-repo analysis, multimodal and algorithmic tasks |
Who Should Read This: Compare Claude 5.5 Sonnet vs Gemini 3.1 Pro for Coding
This comparison is for developers, engineering leads, and technical founders choosing a primary coding model for production work — not casual users comparing chatbots.
If you’re deciding which model to wire into your CI pipeline, your IDE extension, or your coding agent, the sections below are ordered by what actually drives that decision: benchmark reliability, language coverage, context handling, and cost per completed task rather than cost per token.
Testing Methodology and Benchmark Caveats
Benchmark numbers in this article come from Anthropic’s and Google’s own model cards and release documentation, cross-checked against independent evaluation write-ups. Two caveats matter more than the scores themselves.
First, SWE-bench Verified measures one thing: resolving real GitHub issues in Python-heavy open-source repositories. It says little about TypeScript frontend work, SQL query generation, or Rust systems programming. Treat it as a directional signal, not a leaderboard.
Second, benchmark scores don’t capture retry frequency, token efficiency, or how a model behaves when it’s wrong. A model that scores two points higher but silently fabricates a plausible-looking function signature costs you more debugging time than the score suggests.
That’s why the sections below weight real-world editing behavior alongside raw accuracy.
Claude Sonnet 5.5 Overview
Claude Sonnet 5.5 is Anthropic‘s latest Sonnet model, designed for coding, agentic workflows, and complex knowledge work. It builds on Sonnet 5 with stronger coding reliability, faster task completion, and improved performance across long-running agent workflows.
The model is particularly focused on sustained software engineering tasks, including debugging, code editing, refactoring, and multi-step development. Its improvements make it better suited to workflows where the model needs to reason through a task, use tools, and continue working with less human intervention.
Claude Sonnet 5.5 also supports a 1-million-token context window, making it practical for large codebases and lengthy documents. Anthropic positions the model as a strong balance between capability, speed, and cost for everyday professional AI workloads.
With its focus on coding and agentic execution, Sonnet 5.5 is a strong choice for developers who want a capable model for Claude Code, software development, automated workflows, and long-running technical tasks.
Gemini 3.1 Pro Overview
Gemini 3.1 Pro is Google’s new generation large model, which was released in February 2026 as an upgraded version of Gemini 3 Pro.
Compared with the previous version, Gemini 3.1 Pro has stronger reasoning and coding capabilities, as well as multimodal capabilities, and maintains a million-token context window, enabling it to handle large-scale code, documents, images, and other content within a single context.
Compared to other models, Gemini 3.1 Pro demonstrates exceptional prowess in software engineering and algorithmic problem-solving, achieving an outstanding score of 80.6% on the SWE-bench Verified benchmark, ranking among the highest in the industry.
Furthermore, the model’s extended million-token context window enables more comprehensive repository analysis beyond mere single-file processing.
Gemini 3.1 Pro is a large model with powerful reasoning capabilities and agentic features, capable of handling various scenarios such as complex coding, multimodal processing, long-context analysis, and technical research and development.
Coding Architecture: How the Two Models Actually Differ
This is the section most comparisons skip, and it’s the one that actually explains the benchmark gap between the two models.
Claude Sonnet 5.5 favors plan-then-execute methodology. On extended coding sprints it demonstrates tendency to prematurely finalize architectural choices and adhere to them, including naming conventions, file structure and error handling philosophy.
Gemini 3.1 Pro favors context saturation strategy. With 1-million-token context window, it can absorb entire codebases and analyze them alongside supporting documents with minimal need for summarization or iterative review. This allows it to find and replace deprecated function calls throughout large repositories with greater efficiency.
These are both valid approaches to code generation, with Gemini’s 3.1 Pro tending to favor large scale updates and codebase analysis, while Claude’s Sonnet 5.5 focusing on long tail autonomous coding and execution.
Code Quality Comparison
Reviewers consistently describe Claude Sonnet 5.5’s output as more conservative: fewer speculative abstractions, more defensive error handling, and a tendency to write code that a senior engineer would approve in review with minimal comments. This shows up as cleaner diffs, not necessarily shorter ones.
Gemini 3.1 Pro’s output leans more exploratory, especially in front-end and creative-coding contexts — it’s noted for translating vague design intent into working interfaces with less hand-holding.
That flexibility is an asset for prototyping and a liability in codebases with strict style guides, where the extra creative latitude means more review overhead.
Neither model reliably beats the other on raw correctness for typical CRUD, API, or scripting tasks. The gap that matters is in how much cleanup each model’s output needs before merge — and that’s genuinely workflow-dependent.
Reasoning and Debugging Comparison
Debugging is where long-context handling pays off differently than raw reasoning strength. Gemini 3.1 Pro’s 1M-token window means you can hand it a full error log, the relevant service, and its three upstream dependencies in a single prompt, and it will hold all of that without truncation.
Claude Sonnet 5.5 compensates for its smaller default context (200K, with a 1M beta) with what Anthropic calls context tracking — reducing token waste during long sessions so the model doesn’t re-read unchanged files.
In practice, for bugs that are actually one or two files deep, Claude tends to isolate the root cause faster because it’s not distracted by the rest of a million-token window. For genuinely cross-service bugs, Gemini’s window is the more direct fit.
Frontend Comparison
Both models handle React, Vue, and vanilla JS/CSS competently. Gemini 3.1 Pro’s native multimodal training gives it a real edge when a task includes a screenshot or Figma export — it can reason about the image and the code together instead of treating the image as a separate, lossy description.
Claude Sonnet 5.5 tends to produce more consistent component structure across a session, which matters more once a frontend project grows past a handful of files.
Backend Comparison
Backend work — API design, database schema, service boundaries — favors Claude Sonnet 5.5’s plan-then-execute style.
Anthropic’s 30-hour autonomous session data specifically included database setup and application builds, and that stamina shows: Sonnet 5.5 is less likely to drift from an established schema partway through a long backend build.
Gemini 3.1 Pro is competitive on single-session backend tasks but shows more variance on multi-hour autonomous runs.
Language-by-Language Breakdown
| Language | Claude Sonnet 5.5 | Gemini 3.1 Pro | Notes |
|---|---|---|---|
| Python | Strong — primary SWE-bench language | Strong | Near-parity; both trained heavily on Python OSS |
| JavaScript / TypeScript | Strong, consistent typing discipline | Strong, better at design-to-code | Gemini edges out on UI-heavy TS work |
| Java | Solid | Solid | Neither publishes language-specific scores; parity in practice |
| Go | Solid | Solid | Both handle idiomatic Go; edge cases in concurrency need review either way |
| Rust | Competent, more conservative borrow-checker fixes | Competent, more exploratory rewrites | Claude’s conservatism helps here given Rust’s strict compiler |
| C++ | Reliable for standard patterns | Reliable, benefits from long context on large headers | Gemini’s window helps with large C++ codebases specifically |
| SQL | Accurate query generation, cautious with destructive ops | Accurate, occasionally more verbose | Claude asks for confirmation more often on schema-altering queries |
API and Documentation Generation
Both models generate OpenAPI specs, docstrings, and README content reliably. Claude Sonnet 5.5’s reduced shortcut-taking (that 65% figure from Anthropic) matters most here: it’s less likely to write a docstring that describes what a function should do rather than what it actually does.
Gemini 3.1 Pro’s context window is the advantage when generating documentation for an entire package at once, since it can cross-reference every function in scope rather than documenting files in isolation.
Refactoring and Large Repository Analysis
This is Gemini 3.1 Pro’s clearest structural advantage. A 1M-token window can hold a genuinely large repository — hundreds of files — in a single call, which changes what “understand this codebase” means in practice.
Claude Sonnet 5.5’s context is smaller by default, so large-repo work leans more on retrieval and targeted file access rather than whole-repo ingestion. For teams working in monorepos, that’s a real operational difference, not just a spec-sheet number.
That said, context size doesn’t equal context use. A model can hold a million tokens and still lose track of details in the middle of that window — a known failure mode across long-context models generally.
Anthropic’s context-tracking work in Sonnet 5.5 is a direct response to this; Google’s benchmarks on needle-in-a-haystack recall (MRCR-style tests) suggest solid but not perfect retrieval at long lengths. Don’t assume either model reads a million tokens as carefully as it reads the first ten thousand.
Context Window, Latency, and Token Efficiency
Claude Sonnet 5.5 supports a 1M-token context window, while Gemini 3.1 Pro also supports 1M tokens by default. On raw context capacity, neither has a clear advantage. On token efficiency — how much you pay per completed task, not per token — the picture is closer.
Claude’s context handling is designed to support sustained agentic workflows without repeatedly reprocessing unchanged information, which can improve cost efficiency in multi-turn coding sessions even when its output price is higher.
Pricing Comparison
| Claude Sonnet 5.5 | Gemini 3.1 Pro | |
|---|---|---|
| Input (≤200K tokens) | $3 / million | $2 / million |
| Output (≤200K tokens) | $15 / million | $12 / million |
| Above 200K tokens | 1M context beta, separate terms | $4 / $18 per million |
| Free tier | Limited, via Claude.ai | Yes, via Google AI Studio |
At list price, Gemini 3.1 Pro is roughly 20–33% cheaper per token at both ends. Whether that translates into a cheaper task depends on how many turns each model needs to converge on a correct answer — a variable that per-token pricing tables never capture, and one you should measure against your own workload before committing.
IDE Integrations, GitHub Workflow, and Agent Workflows
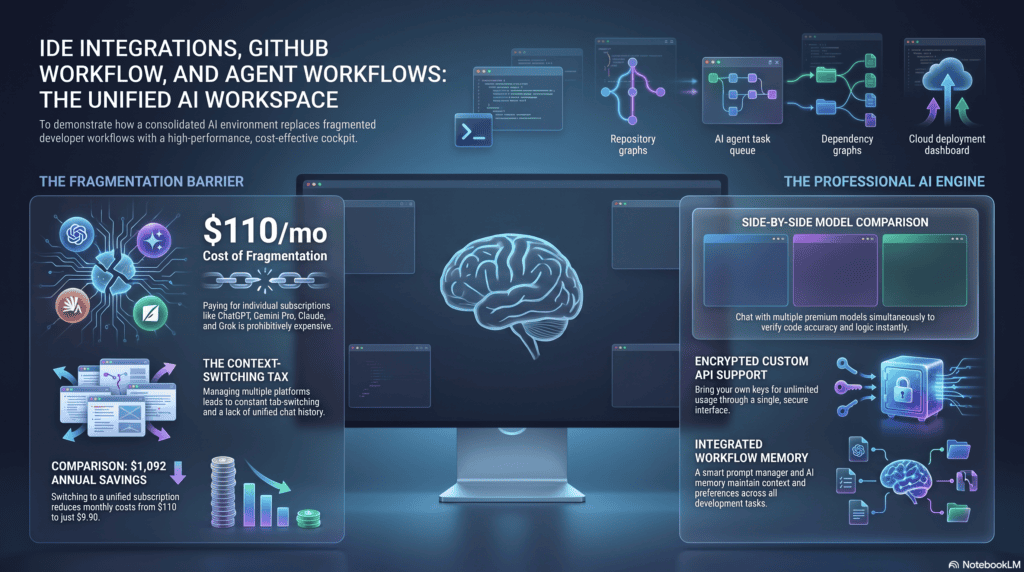
Claude Sonnet 5.5 features a mature agentic tooling ecosystem including Claude Code, VS Code integrations, and Claude Agent SDK providing developers a strong orchestration layer for autonomous coding workflows. So if your workflow is “let the model work independently and review the PR” this is a good option.
Gemini 3.1 Pro on the other hand has broader adoption through Google’s agentic development ecosystem and Vertex AI making it more appealing for teams already using Google Cloud infrastructure. The larger context window also helps for repository-scale analysis and complex multi-step tasks.
Both are available through third-party IDE integrations like Cursor and JetBrains AI Assistant so the day-to-day editor experience is less differentiated than their native tooling might suggest.
Strengths and Weaknesses
Claude Sonnet 5.5
- Strong: sustained autonomous sessions, reliable code editing, consistent architecture across long tasks, mature agent tooling (Claude Code, Agent SDK)
- Weak: higher per-token price, less native multimodal depth, context advantage is less pronounced for very large repositories
Gemini 3.1 Pro
- Strong: 1M-token context, native multimodality, strong algorithmic code generation, advanced reasoning
- Weak: less mature agentic tooling ecosystem, potentially more variation in long autonomous runs, less conservative code style in strict-style-guide teams
Real-World Scenarios
You’re maintaining a 15-year-old monolith with inconsistent conventions. Claude Sonnet 5.5’s discipline and lower error-editing rate reduce the chance of introducing subtle regressions.
You’re analyzing a 300-file monorepo for a cross-cutting refactor. Gemini 3.1 Pro’s context window lets you load more of the repo at once, which matters when the change touches many files with non-obvious dependencies.
You’re building a frontend from a Figma export. Gemini 3.1 Pro’s native multimodal training gives it a direct edge reasoning about the design and the code together.
You’re running an unattended agent overnight on a backend build. Claude Sonnet 5.5’s demonstrated 30-hour autonomous stamina and lower shortcut-taking rate make it the safer default.
You’re cost-constrained and running high volume, simple completions. Gemini 3.1 Pro’s lower per-token pricing adds up fast at scale.
Decision Matrix
| Priority | Recommended Model |
|---|---|
| Long autonomous coding sessions | Claude Sonnet 5.5 |
| Whole-repository / monorepo analysis | Gemini 3.1 Pro |
| Frontend work from design mockups | Gemini 3.1 Pro |
| Backend/infrastructure builds | Claude Sonnet 5.5 |
| Lowest per-token cost | Gemini 3.1 Pro |
| Mature agentic tooling today | Claude Sonnet 5.5 |
| Already on Google Cloud / Vertex AI | Gemini 3.1 Pro |
| Strict code-style, low-review-overhead teams | Claude Sonnet 5.5 |
Who Should Choose Claude Sonnet 5.5
Teams running long, autonomous coding agents, working in disciplined codebases with strict conventions, or already invested in Claude Code should consider Claude Sonnet 5.5. Its strong coding reliability and consistent performance across extended tasks can reduce the review burden on autonomous development work.
Who Should Choose Gemini 3.1 Pro
Teams working with large codebases, doing multimodal or design-to-code work, already using Google Cloud or Vertex AI, or prioritizing advanced reasoning should consider Gemini 3.1 Pro. Its 1M-token context window is a major advantage for analyzing large repositories and complex projects.
FAQ
Is Claude Sonnet 5.5 or Gemini 3.1 Pro better for coding in general? They both have strengths, but Claude Sonnet 5.5 excels at sustained autonomous coding/editing and Gemini 3.1 Pro has an edge in reasoning, larges-context analysis, and multimodal development. It depends on your specific needs and preferences.
Is Gemini 3.1 Pro cheaper for coding tasks? Gemini 3.1 Pro charges $2/$12 per million tokens (input/output) up to 200K context, vs. Claude Sonnet 5.5’s $2/$10. Cost effectiveness depends on your particular tasks, retries, and overall token count.
Is one model better able to handle large codebases? Both models can effectively handle large codebases with their 1M token context windows, but Gemini 3.1 Pro has an edge when needing to simultaneously analyze substantial bodies of code and apply multimodal reasoning.
Is one model more reliable for long autonomous coding sessions? Claude Sonnet 5.5 is excellent for long autonomous coding and the Sonnet iteration specifically emphasized enhanced coding reliability, agentic coding capabilities, and improved multi-step reasoning.
Can Gemini 3.1 Pro process multimodal coding inputs, such as screenshots? Yes! Gemini 3.1 Pro is native multimodal and can process text, images, audio, and video. This makes it particularly valuable for converting screenshots and other referenced materials into code.
What is Claude Sonnet 5.5’s SWE-bench Verified score? Anthropic has not yet officially published Sonnet 5.5’s SWE-bench Verified score, but their model clearly has strong capabilities for coding workflows. As with all models, performance may vary depending on the particular task.
What is Gemini 3.1 Pro’s SWE-bench Verified score? Gemini 3.1 Pro achieved an impressive 80.6% on SWE-bench Verified, according to Google’s official benchmark.
Can I use Claude Sonnet 5.5 and Gemini 3.1 Pro together? Yes! You can use Claude Sonnet 5.5 for coding and Gemini 3.1 Pro for large-context analysis, or vice versa. The two models can complement each other’s strengths.
Is there a better model for Python versus TypeScript or is it the same for both languages? There is not one definitively better model for either language – the similarities vastly outweigh the differences, but individual user preferences may lean one toward Python and another toward TypeScript.
Is there a better model for TypeScript and frontend coding in particular? Both models are proficient with TypeScript and frontend development, but Gemini 3.1 Pro has an edge for design-to-code due to its multimodal capabilities, and Claude Sonnet 5.5 has an edge for sustained frontend component development.
Are these the newest models? Claude Sonnet 5.5 and Gemini 3.1 Pro both represent new iterations in their respective model lines, but were released after the initial comparison was made. Always use the latest information when making a decision about which model to use.
Which model should I use internally within Claude Code or Google Antigravity? Claude Sonnet 5.5 is obviously the best model for use within Claude Code, while Gemini 3.1 Pro is clearly the best option for Google’s Antigravity. Both can also be accessed through a variety of external development tools and platforms.
Can I self-host either of these models? Claude Sonnet 5.5 and Gemini 3.1 Pro are both proprietary models that should be accessed through their respective platforms rather than self-hosted.
Final Verdict
Claude Sonnet 5.5 and Gemini 3.1 Pro represent two different approaches to coding model development, and their relative value cannot be reduced to a simple benchmark score comparison.
The key distinction lies in the fact that Claude Sonnet 5.5 is optimized for reliable, high-throughput agentic workloads and code editing, while Gemini 3.1 Pro combines enhanced reasoning with extended 1M token context and native multimodality.
If your use case is about finding an AI assistant that will perform reliably in complex coding workflows with minimal human intervention, Claude’s Sonnet 5.5 is the right choice.
If your use case is about analyzing large code repositories, combining different types of information, or performing reasoning tasks over extremely long texts, Gemini 3.1 Pro is the right choice. In most cases, it is better to use both models and delegate specific tasks according to their individual characteristics rather than trying to choose between them.
This consideration also helps to improve the technical value of the comparison by providing potential users with practical guidance.
By discussing the specific strengths of each model, its implications for actual code generation and editing, and the supporting evidence (benchmark scores, cost structure, and available features), the comparison helps users make nuanced choices that take their particular circumstances into account.
Author Bio
Jeevesh Tripathi AI Researcher & Technical Writer Email: jeevesh@aizolo.com
Jeevesh is an AI researcher and technical writer specializing in developer-facing evaluations of large language models. His work focuses on translating vendor benchmarks and official documentation into practical, workflow-level guidance for engineering teams choosing between frontier coding models.
He has covered model releases from Anthropic, Google DeepMind, and OpenAI, with an emphasis on verifying claims against primary sources — model cards, API documentation, and official pricing pages — rather than relying on secondhand aggregation.
His technical background spans software engineering and applied AI evaluation, informing a writing style that prioritizes accuracy and honest tradeoff analysis over promotional framing.
Pingback: Does Claude Sonnet 4.5 Have a Limit? Full Guide
Pingback: 7 AI Tools Bundle for Agencies Love Under $30 (2026)