Looking for the cheapest GPT API alternative for solo developers? AiZolo lets you access and compare multiple leading AI models in one workspace.
Test GPT, Claude, Gemini, DeepSeek, and more side by side, helping you find the right model for your workload without switching between separate AI platforms or subscriptions.
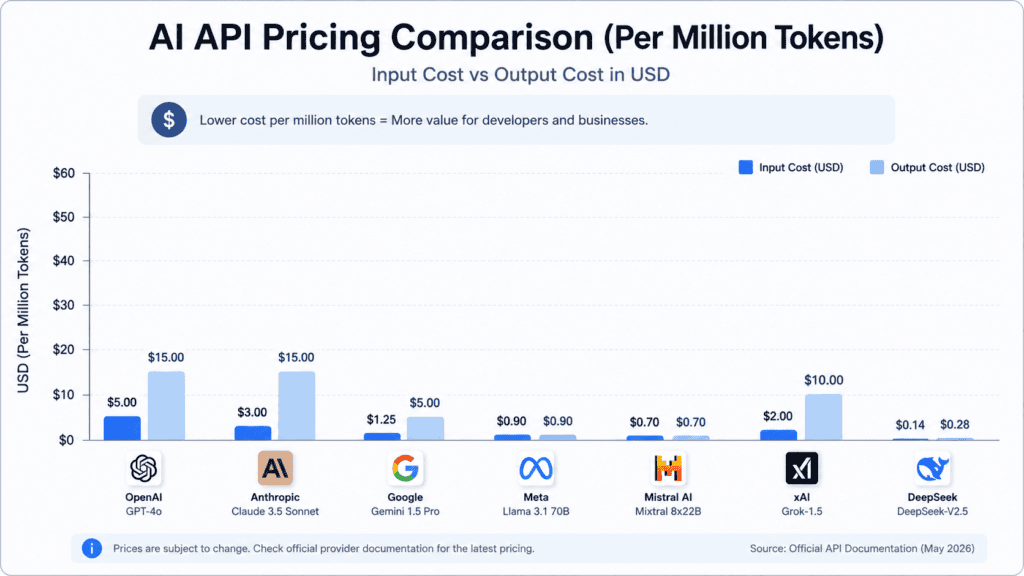
If you’ve watched a token bill creep past your hosting bill, you’re not imagining it. Frontier model pricing moved again in mid-2026, and for a solo developer running a side project or an early-stage SaaS, that shift changes which API actually makes sense to build on.
This guide is not “GPT is expensive, use X instead.” Price alone is a bad filter — a cheap model that fails half your prompts costs more in retries than a pricier model that gets it right the first time.
Instead, this is a real-numbers comparison of what solo developers actually pay across OpenAI, Anthropic’s Claude, Google’s Gemini, xAI’s Grok, Mistral, DeepSeek, and the routing platforms that sit in front of all of them — plus the hidden costs nobody puts in the headline price.
You’ll come away knowing which API is cheapest for your specific workload, what “cheap” actually costs at real usage volumes, and how tools like Aizolo fit in if you’d rather compare and access multiple models from one workspace instead of juggling five separate accounts.
If you’re considering GPT-6 Astra specifically, our GPT-6 Astra review breaks down its pricing, capabilities, coding performance, and where it fits compared with other current AI models.
Table of Contents
What Changed With GPT API Pricing? Cheapest GPT API Alternative for Solo Developers
OpenAI’s latest flagship is GPT-6 Astra, which replaces GPT-5.6 as the model developers should consider when evaluating OpenAI’s highest-end API option.
Astra is designed for complex reasoning, coding, computer use, research, and multi-step professional workflows. It uses the model ID gpt-6-astra in the Responses API and supports up to a 1.05-million-token context window.
The bigger pricing change is significant for solo developers: GPT-6 Astra costs $10 per million input tokens and $50 per million output tokens, making it substantially more expensive per token than the budget APIs discussed later in this guide.
However, OpenAI says Astra can complete some tasks with substantially fewer output tokens than earlier models, so per-token price alone doesn’t tell the whole cost story.
For solo developers, the important number is Astra’s $10/$50 per-million-token pricing. Input tokens are significantly cheaper than output tokens, so applications that generate long responses, run coding agents, or perform multi-step reasoning can accumulate costs quickly.
That makes routing simpler tasks to lower-cost models especially important when building an AI product on a limited budget.
Why Solo Developers Need Cheaper APIs
Bootstrapped SaaS products don’t have a finance team smoothing out surprise invoices. A single indie hacker validating an MVP is usually paying for API calls out of pocket, months before the product earns anything back.
A few situations where API price becomes the deciding factor, not just a nice-to-have:
- Pre-revenue MVP validation — you need to run hundreds of test conversations before you know if the product idea works at all.
- Hobby apps with unpredictable traffic — a Reddit or Product Hunt spike can 50x your normal token volume overnight.
- AI agents and automation workflows — agents call the model repeatedly per task, multiplying token spend far beyond a single chatbot reply.
- Multiple side projects running in parallel — most solo developers aren’t building one app, they’re testing three or four, and the model bill stacks across all of them.
The risk on the other side: picking the cheapest API purely on sticker price and then rebuilding the whole integration three months later because the model can’t hold a function-calling schema together. Price and reliability have to be weighed together — that’s the whole point of this guide.
What Makes an API Truly Affordable?
Sticker price is the input and output rate per million tokens. Real cost is everything around that number.
- Input vs. output cost. Output almost always costs more — 4x to 6x the input rate on most providers. A chatty model with verbose answers can cost more than a “more expensive” model that’s terse.
- Prompt caching. Providers that discount repeated context (system prompts, long documents, few-shot examples) by 90% effectively change your real rate, not just your listed rate.
- Latency and throughput. A model that requires more retries because it times out or gets rate-limited adds cost you won’t see on the pricing page.
- Context window pricing. Some providers charge more once you cross a token threshold (Gemini 3.1 Pro doubles its rate above 200K tokens, for example). If your app regularly sends long context, check for tiered pricing before you commit.
- Scaling behavior. A rate that looks fine at 1M tokens a month can look very different at 100M. Always model your real expected volume, not a demo-sized estimate.
Cheapest GPT API Alternatives: Full Comparison
Prices below are per 1 million tokens (input / output), gathered from provider pricing pages and pricing trackers as of mid-July 2026. Rates change often — always confirm against the provider’s live pricing page before committing budget.
| Provider / Model | Input / 1M | Output / 1M | Context Window | Best For | Notes |
|---|---|---|---|---|---|
| OpenAI GPT-6 Astra | $10.00 | $50.00 | 1.05M | Hard reasoning, coding, agents, computer use | OpenAI’s most capable model |
| Claude Fable 5.1 | $10.00 | $50.00 | — | Advanced coding, knowledge work, research, long-horizon tasks | Latest Fable model; same base pricing as Fable 5, with cheaper cache reads |
| Claude Opus 5 | $5.00 | $25.00 | — | Coding, agents, professional work | Latest Opus model; positioned below Fable 5.1 in Anthropic’s lineup |
| Claude Sonnet 5 | $2.00 | $10.00 | 1M | Coding, agentic workflows | $2/$10 pricing is now permanent, not introductory |
| Claude Haiku 4.5 | $1.00 | $5.00 | 1M | Fast, high-volume tasks | Still active; not the newest Claude generation |
| Gemini 3.8 Flash | $0.75* | $3.75* | 1M | Coding, autonomous agents, enterprise workflows | *Intro pricing through Dec. 31, 2026; standard pricing becomes $1.50/$7.50 in 2027 |
| Gemini 3.5 Flash-Lite | — | — | 1.05M | Extraction, classification, high-volume processing | Current cost-focused 3.5 model |
| Gemini 3.1 Pro | — | — | 1M+ | Complex reasoning, advanced problem solving | Still available as a preview model; not the latest Gemini model overall |
| Grok 4.6 | $2.00 | $6.00 | — | Reasoning, coding, agents, web/X workflows | Replaces Grok 4.5 in your table; current xAI model page updated Sept. 14, 2026 |
| Mistral Medium 3.5 | — | — | — | Agentic and coding workloads | Newer than Mistral Large 3 in Mistral’s current generalist lineup |
| Mistral Large 3 | — | — | — | General-purpose multimodal, open-weight workloads | Still current, but no longer the newest Mistral generalist model |
| DeepSeek V4.1 Flash | $0.15–$0.30† | $0.60–$1.20† | — | High-volume reasoning, coding, multimodal tasks | Replaces DeepSeek V4 Flash; released Sept. 10, 2026 |
| DeepSeek V4 Pro | $0.435* | $0.87* | 1M | Complex reasoning, agents | Best reasoning-per-dollar in this table |
| OpenRouter / Together / Fireworks / Groq | Varies | Varies | Varies | Access to multiple models through one API | Aggregators/inference providers rather than model owners |
Quick read: for solo developers optimizing purely for cost, DeepSeek V4.1 Flash is the cheapest model with genuinely usable quality, and Grok 4.6 is the cheapest option with a large context window. If you want the cheapest first-party US provider option, that’s Claude Haiku 4.5 or Gemini 3.5 Flash-Lite.
Best Alternative for Coding
Claude Sonnet 5 and DeepSeek V4 Pro are the two to shortlist. Sonnet 5 is priced close to Opus-class performance on agentic coding tasks at a fraction of the cost, especially at the $2/$10 introductory rate through August 2026. DeepSeek V4 Pro undercuts it dramatically on price and holds up well on structured coding tasks, making it the pick if your codebase is well-tested and you can tolerate occasional quality gaps.
Best Alternative for AI Agents
Agents make repeated calls per task, so output-token efficiency matters more than headline price. Grok 4.6 costs substantially less per output token than GPT-6 Astra, while Claude Sonnet 5 remains a strong option because Anthropic’s tool-use and function-calling implementation is mature and well-documented.
Best Alternative for Chatbots
Chatbots are output-heavy and latency-sensitive. Gemini 3.8 Flash ($1.50/$9) is a good middle ground — cheaper than most flagships, fast, and includes native Google Search grounding for up-to-date answers. Claude Haiku 4.5 is the cheaper fallback for simpler conversational flows.
Best Alternative for Automation
Automation and workflow tasks (classification, extraction, routing, summarization) rarely need a flagship model. DeepSeek V4 Flash or Gemini 3.5 Flash-Lite handle these at a fraction of flagship cost — this is the highest-leverage place to cut spend without hurting product quality.
Best Open Source Option
DeepSeek V4 (Flash and Pro) is the clear open-weight leader on price-to-capability right now, available directly from DeepSeek or through aggregators like OpenRouter, Together AI, and Fireworks AI, which trade a small price premium for better global latency and uptime.
Real Cost Comparison: What You’ll Actually Pay
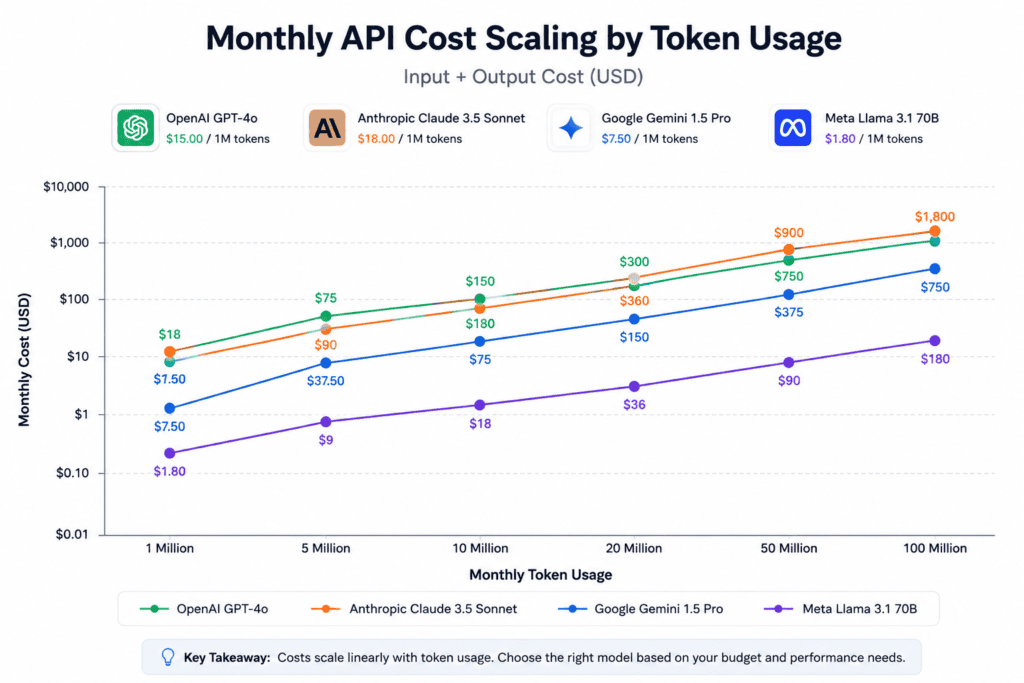
Estimates below assume a common solo-developer traffic pattern: 60% input tokens, 40% output tokens, no caching applied (caching would lower these numbers by up to 90% on repeated context).
| Monthly Volume | GPT-6 Astra | Claude Sonnet 5 (standard) | Gemini 3.8 Flash | DeepSeek V4 Flash |
|---|---|---|---|---|
| 1M tokens | ~$26 | ~$7.80 | ~$4.50 | ~$0.19 |
| 5M tokens | ~$130 | ~$39.00 | ~$22.50 | ~$0.95 |
| 20M tokens | ~$520 | ~$156.00 | ~$90.00 | ~$3.80 |
| 100M tokens | ~$2,600 | ~$780.00 | ~$450.00 | ~$19.00 |
Key takeaway: the gap between a flagship model and a budget model widens fast as volume scales. At 100M tokens a month, GPT-6 Astra costs about $2,600 versus just $19 for DeepSeek V4 Flash — a difference of roughly $2,581, making a strong case for routing simple tasks to a cheaper model instead of defaulting everything to the flagship.
Hidden Costs Developers Ignore
The per-token rate is only part of the bill. These add up quietly:
- Retries. A failed or malformed response that you retry doubles the cost of that call — and flaky models retry more often.
- Output inflation. Verbose models generate more output tokens per answer than terse ones, even for the same question.
- Long-context surcharges. GPT-6 Astra also applies higher rates to prompts above 272K input tokens, making long-context workloads particularly important to model carefully before committing to the API.
- Reasoning tokens. “Thinking” or reasoning tokens on models with extended reasoning modes are billed as output tokens, even though they never reach the user.
- Vector storage and embeddings. If you’re running RAG, embedding generation and vector database costs sit alongside the completion API bill.
- Monitoring and observability tooling. Once you’re tracking cost per request across models, that tooling itself often has a monthly fee.
API Cost Optimization Strategies
- Prompt caching. Cache system prompts, long documents, and repeated few-shot examples — most providers discount cache hits by up to 90%.
- Batch processing. Non-real-time work (report generation, bulk classification) usually qualifies for a 50% batch discount on OpenAI, Anthropic, and Google.
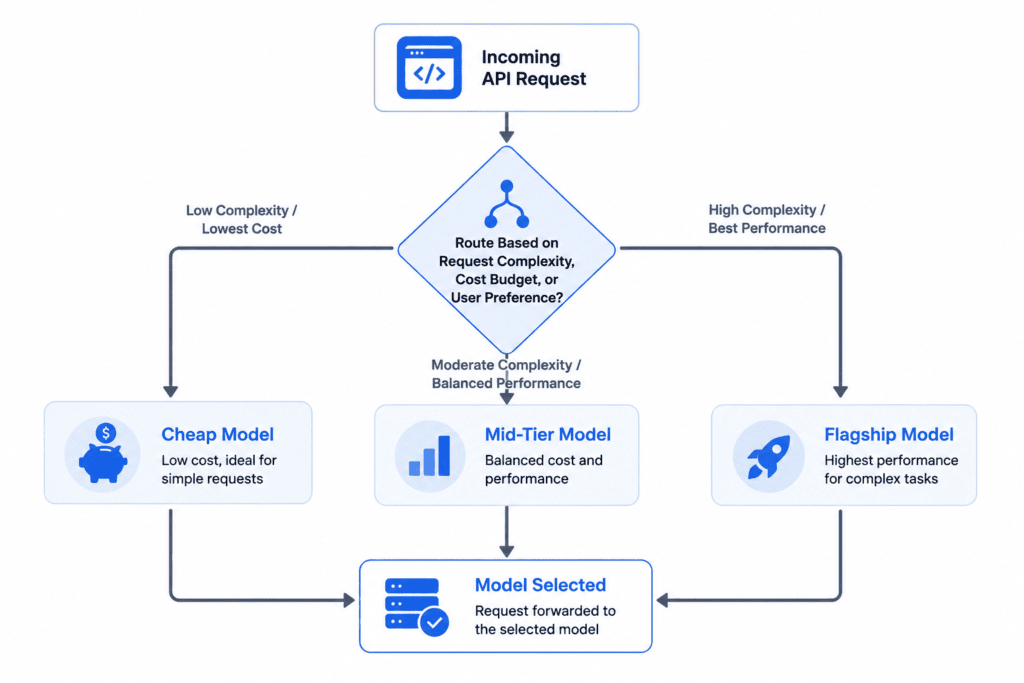
- Model routing. Send simple requests to a cheap model and escalate only the hard cases to a flagship model — a common pattern is roughly 60% of traffic to a budget tier, 35% to a mid tier, and 5% to the flagship.
- Prompt optimization. Shorter, more specific prompts reduce both input tokens and the chance of a verbose, expensive response.
- Context trimming. Don’t send your entire conversation history on every call if the model doesn’t need it — trim to what’s relevant.
- Hybrid model strategies. Use a cheap model for a first pass (extraction, classification) and a stronger model only for the step that actually needs reasoning.
Cutting Token Waste: A Practical Example
Optimization strategies are easy to state and easy to skip. Here’s what they look like on an actual request.
Unoptimized prompt (~1,240 tokens):
A verbose instruction that restates the task, adds unnecessary politeness framing, and repeats context already implied by the system prompt.
Trimmed prompt (~340 tokens):
A direct instruction, the raw input, and an explicit output format (bullet points, fixed fields) so the model doesn’t pad the response with unrequested explanation.
That single change cuts roughly 70% of input tokens on that request — before caching or model routing even enter the picture. Two habits do most of the work:
- Specify output format explicitly. “Return: issue summary, solution steps, escalation (yes/no)” produces a shorter, cheaper response than an open-ended ask.
- Cap output length at the API level, not just in the prompt:
```python
response = client.messages.create(
model="claude-haiku-4-5",
messages=[…],
max_tokens=500, # hard ceiling on output cost
)
```
Most tasks — classification, extraction, short-form generation — don’t need a 2,000-token ceiling. Setting max_tokens deliberately, rather than leaving the default, is one of the few optimizations that costs nothing to implement and pays back on every single call.
Common Mistakes That Erase Your Savings
Even developers who’ve read every pricing page make these:
- Defaulting to the flagship model for everything. The single biggest line-item mistake — routing simple classification or extraction through a $5/$30 model instead of a $0.25–$1 tier.
- Letting prompts drift. Small wording changes between otherwise-identical requests break cache hits silently — you keep paying full price and never notice why caching “isn’t working.”
- Skipping a hard output cap. Without
max_tokens, a model with room to elaborate will use it, and output tokens are the expensive side of every request. - Treating token volume as the whole cost model for agents. Agentic workflows scale with call count per task, not just tokens per call — budget per completed task, not per token, or the estimate will be wrong.
- Reviewing pricing once and never again. Provider rates moved multiple times in the first half of 2026 alone; a “cheapest option” audit from six months ago is probably stale.
A Simple Action Plan
- Audit — pull last month’s usage by request type and flag which ones are currently running on a flagship-tier model.
- Reroute — move classification, extraction, and short-form tasks to a budget tier (DeepSeek V4 Flash, Gemini 3.1 Flash-Lite, or Claude Haiku 4.5).
- Cap and cache — set
max_tokenson every call, and standardize system prompts so caching actually triggers. - Re-check monthly — pricing shifts often enough that a routing setup built in Q1 may be leaving savings on the table by Q3.
When GPT Is Still Worth Paying For
GPT-6 Astra is positioned by OpenAI for the hardest end-to-end workloads, including complex reasoning, software engineering, computer use, research, and professional work. It also supports advanced capabilities such as computer use, structured outputs, tool calling, prompt caching, persisted reasoning, and multi-agent orchestration.
For solo developers, the question is therefore not simply whether Astra is expensive, but whether its capabilities reduce enough development time, retries, or output volume to justify its higher API cost.
The point of this guide isn’t “never use GPT” — it’s “don’t default to the most expensive tier out of habit.”
Decision Matrix
| Priority | Recommended API |
|---|---|
| Absolute lowest cost | DeepSeek V4.1 Flash |
| Lowest cost with large context | Grok 4.6 |
| Best coding value | Claude Sonnet 5 or DeepSeek V4.1 Flash |
| Best for AI agents | Grok 4.6 or Claude Fable 5.1 |
| Best for chatbots | Gemini 3.8 Flash |
| Best for customer support automation | Gemini 3.5 Flash-Lite or DeepSeek V4.1 Flash |
| Best for startups scaling fast | Claude Sonnet 5 with Haiku 4.5 routing |
| Best for enterprise-grade reliability | Claude Opus 5 or GPT-6 Astra |
| Want to compare models without juggling accounts | AiZolo — access multiple leading AI models from one workspace |
Frequently Asked Questions
What is the cheapest alternative to the GPT API in 2026? DeepSeek V4 Flash is currently the cheapest usable option at $0.14 input / $0.28 output per million tokens, dramatically undercutting OpenAI, Anthropic, and Google’s flagship rates.
Is Claude cheaper than GPT for solo developers? Claude Haiku 4.5 ($1/$5 per million tokens) is cheaper than GPT-6 Astra, while Claude Sonnet 5 ($2/$10 per million tokens) also undercuts GPT-6 Astra on both input and output cost.
Is Gemini cheaper than GPT-6 Astra? Yes, for most tiers. Gemini 3.5 Flash-Lite ($0.25/$1.50) and Gemini 3.8 Flash ($0.75/$3.75) both undercut GPT-6 Astra on a per-token basis, though Gemini’s Pro tier adds a surcharge above 200K tokens of context.
What’s the cheapest API with a large context window? Grok 4.6 offers a large context window at competitive pricing, making it one of the most affordable large-context options currently available.
Should a solo developer use an open-source model like DeepSeek? For cost-sensitive, high-volume workloads, yes — DeepSeek V4.1 Flash offers strong price-to-capability value. For tasks requiring reliable tool use and structured outputs, a first-party model like Claude or GPT-6 Astra may still be worth the premium.
Does prompt caching actually save meaningful money? Yes. Most providers discount cached input tokens by up to 90%, which matters a lot for repeated system prompts, long documents, or few-shot examples reused across many requests.
What’s the difference between input and output token pricing? Input tokens are what you send to the model (your prompt and context); output tokens are what the model generates back. Output almost always costs more — often 4x to 6x the input rate.
Is OpenRouter cheaper than going direct to a provider? Sometimes. Aggregators like OpenRouter, Together AI, and Fireworks AI can offer competitive or even lower rates on open models, but pricing varies by provider and model — always compare against the model owner’s direct rate.
What is the real cost of running an AI agent at scale? Agents make multiple model calls per task, so costs scale with call count, not just token volume. Budgeting per completed task (not just per token) gives a more accurate picture for agentic workloads.
Are batch APIs worth using for a side project? If your workload isn’t real-time — report generation, bulk classification, content generation — batch APIs typically cut costs by 50% on major providers, making them worth using whenever latency isn’t critical.
Do I need function calling or structured outputs for my API choice to matter? If your app relies on reliable JSON output or tool calling, model choice matters more than price alone — some cheaper models are less consistent at following strict output schemas.
What is prompt caching and how does it work? Prompt caching stores frequently reused content (system prompts, documents, examples) so repeated requests don’t pay full price for the same context, typically cutting cached-input cost by up to 90%.
Is it cheaper to build my own model routing or use a platform that does it for me? Building your own router gives full control but takes engineering time; a platform like Aizolo that lets you access and compare multiple models from one workspace can save that setup time for solo developers who’d rather ship than maintain routing logic.
How often does AI API pricing change? Frequently — several providers adjusted pricing in the first half of 2026 alone. Always check the official pricing page before finalizing a budget, since third-party comparisons (including this one) can lag provider updates.
What’s the single biggest cost mistake solo developers make? Defaulting every request to the most capable (and most expensive) model available, instead of routing simple tasks to a cheaper tier and reserving the flagship for genuinely hard problems.
Conclusion
There’s no single “cheapest” API — there’s a cheapest API for your specific workload. DeepSeek V4.1 Flash offers very low pricing. Grok 4.6 offers competitive pricing for large-context workloads. Claude Sonnet 5 and Gemini 3.8 Flash offer strong price-to-capability options for coding and chat, respectively. The right move for most solo developers is routing: cheap models for the easy 80% of requests, a stronger model reserved for the hard 20%.
If comparing all of this manually across five provider dashboards sounds like more work than building your actual product, that’s exactly the gap AiZolo is built to close — one workspace to access and compare multiple leading AI models instead of juggling separate accounts, keys, and pricing pages.
Author Bio
Author: Jeevesh Tripathi Email: jeevesh@aizolo.com
Jeevesh Tripathi researches AI models, LLM API pricing, and developer tooling, tracking how token costs, context windows, and provider pricing structures shift across OpenAI, Anthropic, Google, xAI, Mistral, and DeepSeek. His work focuses on helping indie developers and early-stage SaaS teams make cost-effective decisions about their AI stack.